Otto Otto · 24 September 2026
How Specialized Platforms Handle Data Flow in Peak Times Using Predictive Caching in Cloud Environments
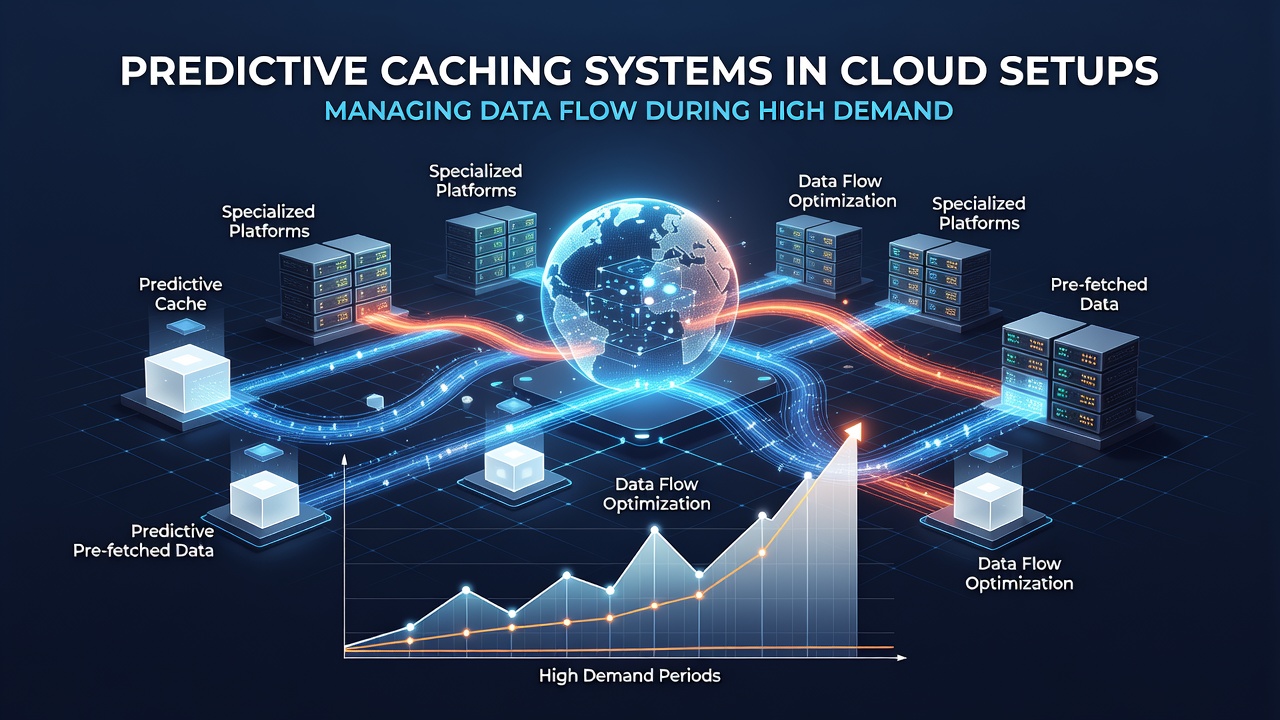
Specialized platforms rely on predictive caching systems to maintain steady data flow when user demand surges, and these setups operate within cloud infrastructures that scale resources dynamically. Researchers have documented how algorithms analyze historical access patterns to preload content into cache layers before traffic peaks arrive, which reduces latency and prevents bottlenecks at origin servers. Data shows that such systems integrate machine learning models trained on metrics like request frequency, time of day, and geographic distribution to forecast needs with increasing accuracy over successive cycles.
Cloud providers equip these platforms with distributed cache nodes positioned across global regions, and this architecture allows content to sit closer to end users while the predictive layer decides what to retain or evict based on projected load. Studies from academic institutions indicate that platforms processing streaming media or real-time analytics achieve measurable improvements in throughput when caching decisions shift from reactive to anticipatory rules. Observers note that the shift becomes particularly relevant during events that generate sudden volume increases, such as live broadcasts or scheduled software releases.
Core Mechanisms Behind Predictive Caching
Algorithms first collect telemetry from multiple sources including server logs, network traffic counters, and user session data, then feed those streams into models that output probability scores for individual data objects. When scores exceed defined thresholds the system fetches and stores copies in memory or solid-state caches distributed throughout the cloud fabric. This process runs continuously in background tasks, and it adjusts parameters automatically as new patterns emerge from ongoing operations.
Engineers configure eviction policies that balance freshness against hit rates, and these policies often combine least-recently-used rules with predictive decay functions that lower priority for items unlikely to appear in upcoming demand windows. Research indicates that hybrid approaches yield better results than purely statistical methods because they incorporate real-time signals alongside long-term forecasts. Platforms therefore maintain separate cache tiers, with the top tier reserved for high-confidence predictions and lower tiers holding fallback content.
Handling Traffic Surges in Practice
During periods of elevated demand the predictive layer activates additional cache instances through cloud orchestration APIs, and this scaling occurs minutes before actual load materializes. One documented case involved a content delivery network that used weather and event calendars to anticipate regional spikes, allowing it to preposition video segments in edge locations hours ahead of time. Figures from industry reports reveal that such pre-positioning can cut origin server queries by more than half during peak windows.
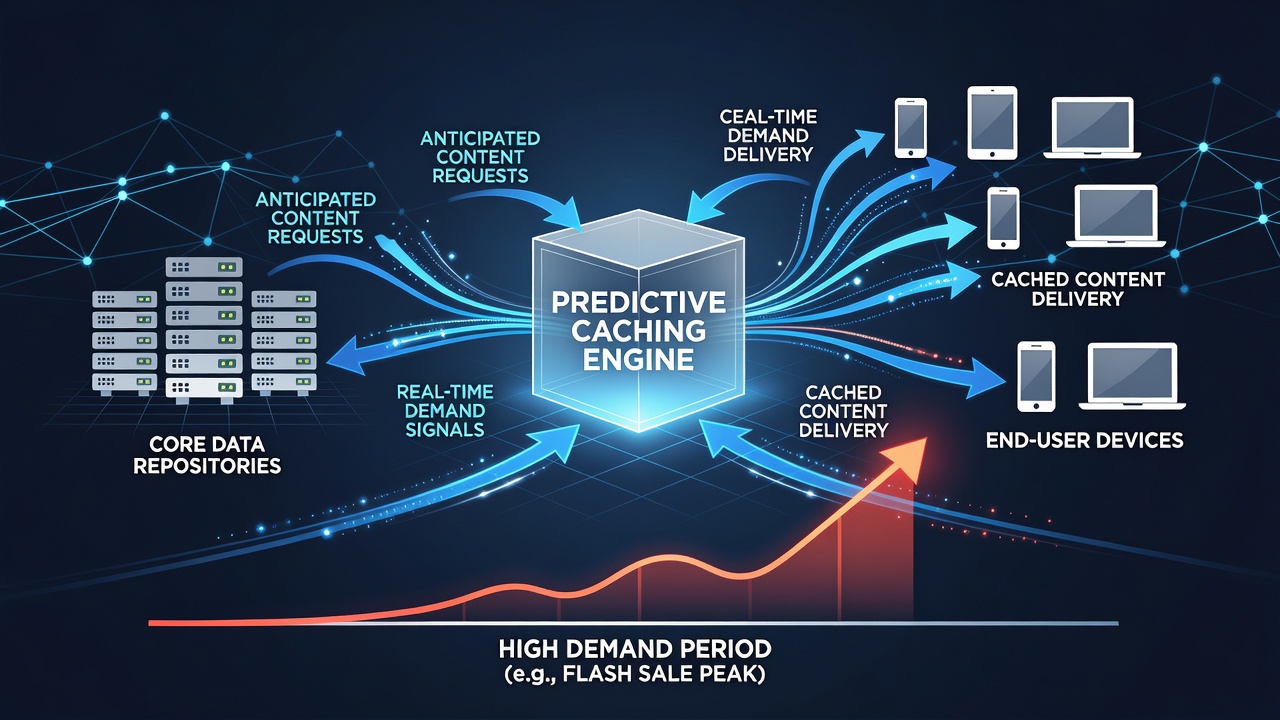
Coordination between caching services and underlying compute clusters ensures that storage allocation expands in tandem with compute reservations, preventing situations where cached data exists but cannot be served quickly enough. Canadian research groups have published analyses showing that synchronization latency between these components directly influences overall system stability when demand multiplies within short intervals. Platforms therefore embed heartbeat checks that trigger corrective actions if synchronization lags exceed preset limits.
Integration With Broader Cloud Infrastructure
Modern implementations connect predictive caches to container orchestration platforms and serverless functions that execute model inference on demand. This linkage allows the cache layer to react to signals generated by auto-scaling groups without manual intervention. According to data released by the European Telecommunications Standards Institute, standardized interfaces between cache controllers and cloud resource managers have reduced deployment times for new prediction rules from days to hours in tested environments.
Security controls remain active throughout these operations, and platforms apply encryption at rest plus access logging to every cached object. Government guidelines from Australia recommend regular audits of prediction models to verify that they do not inadvertently prioritize certain data types over others, thereby preserving equitable service delivery across user segments. Such oversight becomes routine as regulatory expectations evolve through 2026.
Performance Metrics and Observed Outcomes
Teams track cache hit ratios, time-to-first-byte, and origin offload percentages as primary indicators of system health. When predictive accuracy improves, these numbers rise together, and platforms often publish aggregated statistics that demonstrate year-over-year gains. One study covering multiple cloud regions found that hit ratios above 85 percent correlated with consistent user experience scores even when total request volume doubled within an hour.
Maintenance routines include periodic retraining of the underlying models using fresh datasets collected from production traffic, and this cycle prevents drift that would otherwise degrade forecast quality. Platforms schedule these updates during low-traffic windows to minimize disruption, and they run parallel shadow deployments that compare new model outputs against existing ones before full rollout.
Conclusion
Predictive caching in cloud environments has become a standard approach for specialized platforms facing variable demand, and its continued refinement depends on tighter integration between data science practices and infrastructure automation. As traffic patterns grow more complex through 2026, the same principles of anticipation and pre-positioning are expected to extend into additional service categories beyond media delivery and analytics. The documented results from current deployments provide a baseline against which future enhancements can be measured.